
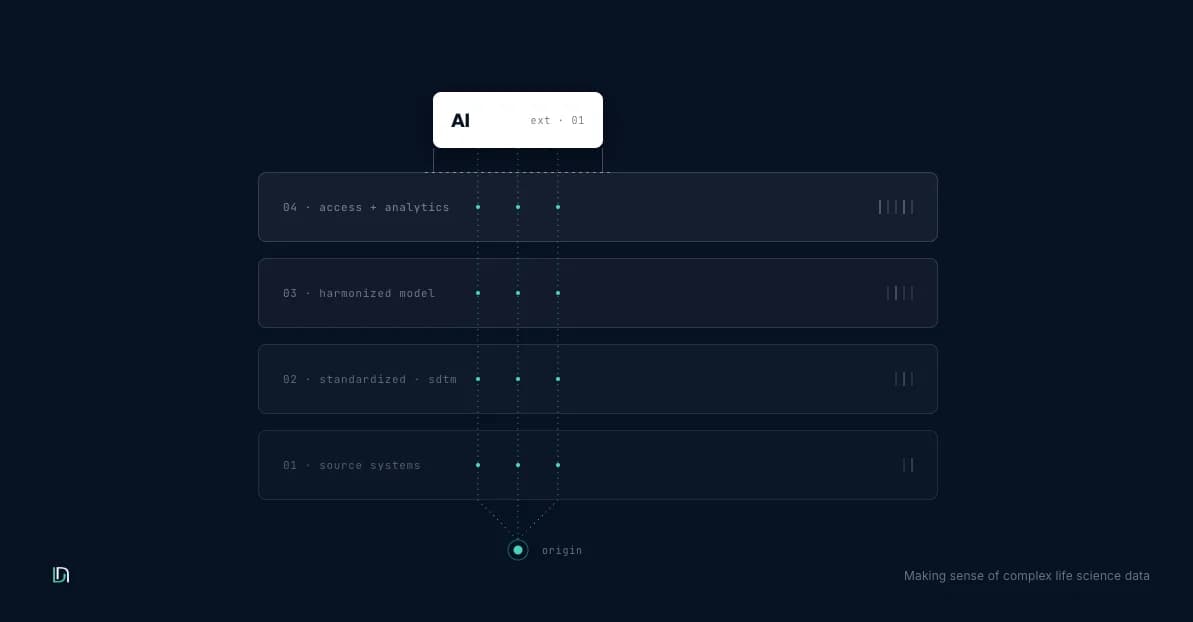
Bringing an external AI capability into a life sciences organization can mean connecting a discovery model, a single-cell analysis platform, or an assistant hosted on a cloud platform to internal systems. The model may perform well in a demonstration. Integrating it with the organization’s data and controls is a separate delivery task.
Then the real work starts, and it involves both the model and the environment around it.
The hard part is wiring someone else's AI into a regulated internal data environment without losing track of where the data came from, what the model did with it, and who can answer for the output when a regulator or an auditor asks. The challenge is not only proving that an AI capability works. It is also governing and scaling it on data you can trust and trace.
The data layer is part of the AI evaluation
A model that performs well on a benchmark may still fail against a particular dataset or workflow. Evaluation therefore has two parts: whether the model is suitable for its intended use, and whether the data layer can supply the inputs, permissions, and provenance that use requires.
Gartner’s February 2025 research forecast 60% abandonment through 2026 among AI projects without AI-ready data. It also reported a July 2024 survey of 1,203 data leaders, not 248, in which 63% lacked confidence in or appropriate AI data practices. Neither finding measures clinical-model failure or establishes that algorithms are rarely at fault.
An external model makes this sharper, not softer. When you connect an outside AI platform to your internal data, you inherit two things at once: a capability you did not build, and a new set of questions about lineage, access, and accountability that your existing controls were never designed to answer.
Why external AI raises the governance stakes
Adoption can run ahead of control. In EY’s March 2026 release on a poll of 500 US technology-industry leaders, 78 percent reported that AI uptake was outpacing their ability to manage it, and 52 percent said department-level initiatives operated without formal approval or oversight. Forty-five percent reported confirmed or suspected sensitive-data leaks through unauthorized third-party AI tools in the previous year. This was a technology-industry poll, not a life sciences incident-rate study.
In a regulated environment, these are data integrity and accountability concerns. If an external model touches clinical, safety, or market access data, the organization needs clear ownership of its inputs, transformations, and approved use. In McKinsey’s March 2025 report, 28 percent of respondents at AI-using organizations assigned AI-governance oversight to their CEO and 17 percent to their board. Ownership was often shared. These percentages do not mean the remaining organizations had no governance.
What keeping control actually requires
Teams that bring external AI inside without losing control tend to treat governance as an engineering surface, not a policy document. In practice that means a small number of concrete capabilities.
Source versioning and lineage should let a reviewer identify the inputs and transformations behind an output. Access controls should cover the model and its tools, not stop at the database. Define a risk-based audit-event scope for relevant reads, writes, model calls, approvals, and access changes. Record model and prompt versions, configuration, tool results, and retained output where appropriate, while minimizing sensitive content in logs. These records support investigation and reproducibility testing; they do not guarantee an identical rerun from a changing or nondeterministic external service.
None of this is exotic. Governance tooling can capture lineage and enforce controls for supported integrations. Teams still need to check coverage across external APIs, custom transformations, model endpoints, and tools. The reason it still breaks is that most environments bolt the external model onto the side of a data estate that was never traceable in the first place. The tooling can only govern what the underlying architecture exposes.
Where the work tends to land
A substantial part of this work can land in the data layer, alongside model evaluation and application controls. This is the part that is easy to underestimate when the external platform looks ready to go.
A useful way to see it: a domain-specific AI agent is only as trustworthy as the fields it can reach. Recent engineering work on a life sciences AI query agent expanded structured data coverage roughly tenfold and cut query time by about 35 percent, but the result came from curating more than 250 fields into a governed, queryable layer first. The agent was the last mile. The foundation was the project. The same pattern shows up in consolidation work, where a post-merger AWS-to-Azure migration of around 2.5TB of platform data in total, with zero major downtime, mattered less for the migration itself than for the traceable, governed environment it left behind.
The lesson repeats across CROs, pharma, biotech, and digital health. External AI does not fix a disconnected data estate. It exposes it faster.
Most life sciences teams do not want to buy a governance platform. They want to put an external model to work without a risk event, and without waiting on a multi-year rebuild. A focused four-to-six-week engagement can be scoped to map the data a selected model will touch, identify lineage and access gaps, and demonstrate a bounded governed workflow. Access, provider capabilities, risk review, and the intended use determine what can be completed in that period. Production approval remains a separate decision.
Final Thought
A lot of what looks like an AI decision in 2026 is really a data governance decision wearing a model's face.
The organizations bringing external AI inside successfully are not the ones with the best models. They are the ones who can still answer, at any moment, where the data came from and what the model did with it. That ability lives in the data layer, and it is built before the model arrives, not after.
For implementation support, see DataDrill’s AI solutions for life sciences. The articles on evidence-grade data and agent-ready data cover the two adjacent requirements: defensible outputs and a governed data foundation.